Summarize with AI


Perplexity AI introduced JOLT, a reinforcement learning method that trains a single model simultaneously as both student and teacher to accelerate reasoning on multi-step tasks.
Standard reinforcement learning provides only sparse feedback at the end of an episode, leaving multi-step agent actions without intermediate guidance. Traditional distillation methods rely on a separate teacher model, which often reasons too far ahead for the student model to bridge the gap.
Under JOLT, the teacher receives the ground-truth solution or previous execution logs while the student executes blindly. Both roles share model weights and update simultaneously. The teacher learns to provide step-by-step guidance calibrated directly to the student's current capability. In an extended formulation called JOLT+, the student receives both teacher hints and terminal reward signals.
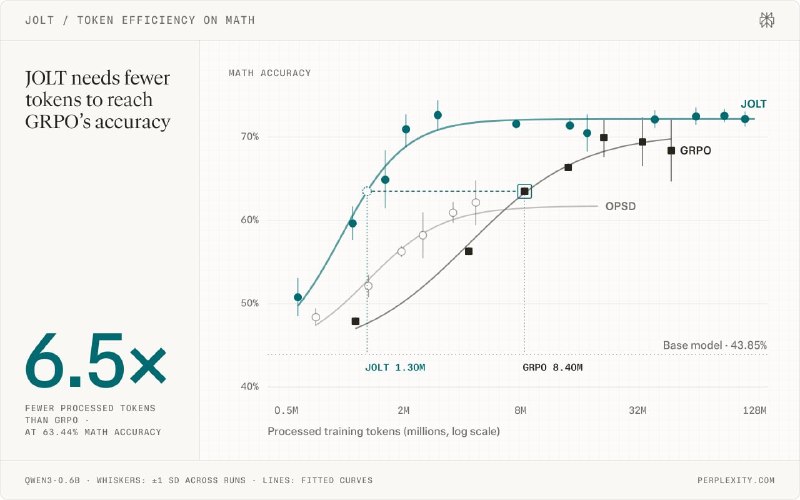
Perplexity tested JOLT on models from 0.6B to 30B parameters across DeepSeek and Qwen architectures. On the MATH benchmark, JOLT+ outperformed GRPO by 4.2 percentage points while consuming 6.5 times fewer training tokens and 13 times fewer generated tokens. On LiveCodeBench and AppWorld, JOLT+ gained 3.0 and 9.9 percentage points over GRPO respectively.
What it is
- Shared weights: A single neural network acts as both teacher and student during training.
- Asymmetric information: The teacher inspects ground-truth steps or past attempts, while the student solves problems unassisted.
- Adaptive hints: The teacher optimizes its intermediate guidance to match the student's exact learning trajectory.
- Sample efficiency: JOLT matched baseline accuracy on MATH while reducing training token volume by 6.5x.
Sources
Did this land? Leave a reaction.
Discussion
0 commentsMembers can join the discussion
Become a member to comment and reply to other members.
Become a MemberNo comments yet
Be the first to start the discussion.