Summarize with AI


NVIDIA published weights for Nemotron 3.5 Bolt E4B, a compact 8-billion parameter model optimized for on-device deployment across GeForce RTX graphics cards, Jetson embedded boards, and Spark edge computers.
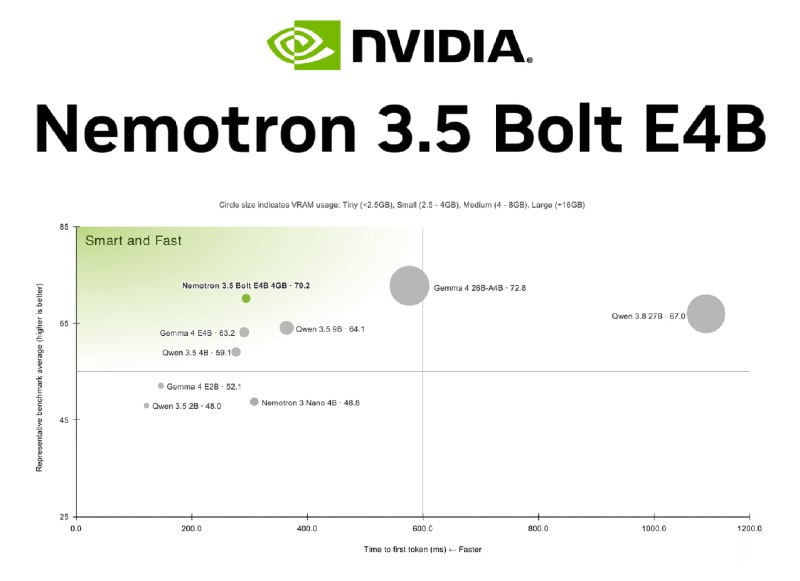
The release follows the launch of Nemotron 3.5 Super VL and its 74B Bolt variant. Unlike the larger Bolt, Bolt E4B is derived from Google's Gemma 4 E4B, fine-tuned by NVIDIA using reinforcement learning for instruction following, multi-step tool calling, and dialogue.
What it is
- Hybrid parameter architecture. Bolt E4B contains 8 billion total parameters, activating 4 billion parameters per token with a 64,000-token context window and support for 35 languages.
- Low memory footprint. 4-bit quantization reduces memory consumption to approximately 4 GB of VRAM.
- Configurable reasoning. Reasoning modes can be toggled on or off, and reasoning step length can be bounded to maximize throughput.
- Hardware benchmarks. On a desktop GeForce RTX 5070, time-to-first-token is 548 milliseconds with generation speeds reaching 133 tokens per second. On a Jetson Orin Nano edge board, time-to-first-token is 5.8 seconds at 15.5 tokens per second.
- Speculative decoding support. NVIDIA released companion draft models using the DFlash speculative decoding technique, yielding up to a 21% inference speedup.
- Ecosystem integration. Checkpoints in BF16 and GGUF formats are available on Hugging Face, with immediate runtime support in Ollama, llama.cpp, LM Studio, vLLM, and SGLang under the OpenMDW 1.1 license.
Benchmark comparisons
| Benchmark / Metric | Nemotron 3.5 Bolt E4B | Gemma 4 E4B | Qwen3.5 4B |
|---|---|---|---|
| Total Parameters | 8B (4B active per token) | 8B (4B active) | 4B |
| Context Window | 64,000 tokens | 64,000 tokens | 32,000 tokens |
| Memory Footprint (4-bit) | ~4 GB | ~4 GB | ~2.5 GB |
| Tau2-Bench (Tool Calling) | 52.3 | 48.1 | 61.7 |
| RULER (Long Context) | 85.8 | 80.2 | 95.4 |
| Average Token Efficiency | Up to 80% fewer tokens vs Nano 3 | Baseline | Baseline |
Sources
Did this land? Leave a reaction.
Discussion
0 commentsMembers can join the discussion
Become a member to comment and reply to other members.
Become a MemberNo comments yet
Be the first to start the discussion.