Summarize with AI


MIT researchers introduced SwaT (Swarm Telepathy), an architecture that enables multi-agent AI systems to communicate by exchanging key-value cache directly rather than generating text summaries.
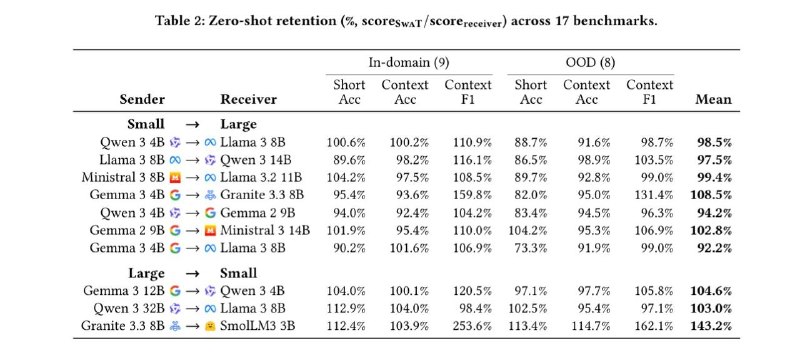
Traditional multi-agent pipelines require models to summarize intermediate findings into natural language strings, incurring redundant prefill computations and losing nuanced contextual details. SwaT establishes prefill-free context transfer even across different model families.
What it is
- Cross-family KV-cache transfer. SwaT allows heterogeneous language models from different families to share precomputed attention states directly without fine-tuning either model.
- Significant speed and accuracy gains. When paired with KV-cache compaction, SwaT achieves a 40% average improvement in answer accuracy and a 4x reduction in wall-clock latency compared to text-based summaries.
- Cross-modal capability transfer. Vision-Language Models (VLMs) can transfer visual context directly into text-only language models via SwaT, bypassing intermediate text descriptions despite being trained purely on textual data.
- Frozen weights and low training overhead. Both sender and receiver LLMs remain entirely frozen; training the SwaT connector requires fewer than 50 million tokens and under one GPU-day.
- Extensive validation. Researchers validated the architecture across 17 distinct evaluation benchmarks covering 12 large language models spanning six architecture families.
Communication architecture comparison
| Feature | Text Summaries (Baseline) | SwaT (Swarm Telepathy) |
|---|---|---|
| Communication medium | Discrete token strings | Continuous KV cache |
| Receiver prefill cost | Full recomputation required | Prefill-free instant transfer |
| Relative accuracy | Baseline (1.0x) | +40% mean accuracy |
| Wall-clock speed | Baseline (1.0x) | 4x faster execution |
| Vision transfer to text LLMs | Textual descriptions only | Direct visual cache ingestion |
| Model weights | Frozen or fine-tuned | 100% frozen (under 1 GPU-day training) |
Sources
Did this land? Leave a reaction.
Discussion
0 commentsMembers can join the discussion
Become a member to comment and reply to other members.
Become a MemberNo comments yet
Be the first to start the discussion.