
Summarize with AI


MiniMax has released the open weights for M3.1 Flash, a 428 billion parameter Mixture-of-Experts foundation model optimized for multi-step agent workflows, computer tool use, and automated code generation. The architecture activates approximately 23 billion parameters per token.
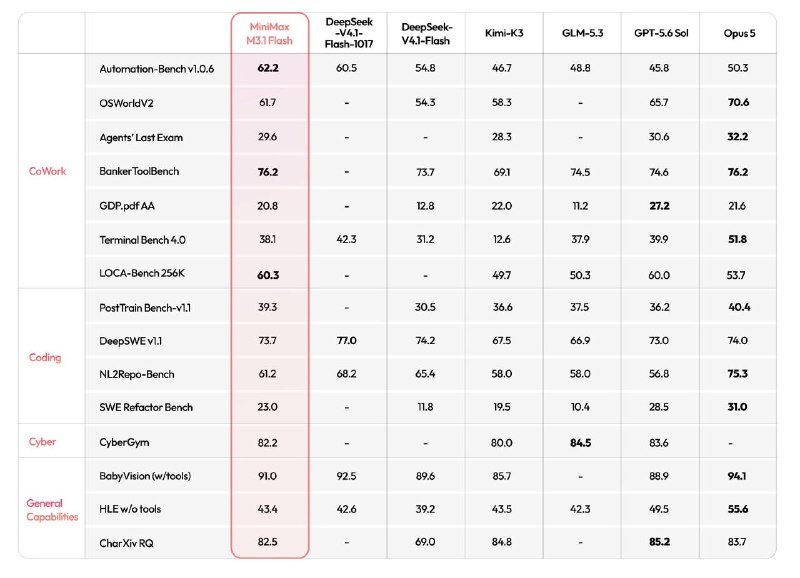
The model leverages MiniMax Sparse Attention paired with DSpark speculative decoding to accelerate generation throughput during execution. According to evaluations published by MiniMax, M3.1 Flash scored 73.7% on the DeepSWE v1.1 engineering benchmark and 61.7% on OSWorld V2 for desktop interface navigation.
What it is
- 428B MoE architecture. The model routes requests across specialized experts, activating 23 billion parameters per token to balance reasoning capacity with serving cost.
- Agent benchmarks. Evaluated scores include 76.2% on BankerToolBench for financial API interactions, 82.2% on CyberGym for vulnerability recreation, and 29.6% on Agents' Last Exam.
- Inference acceleration. Features native MiniMax Sparse Attention and a dedicated DSpark drafting network for speculative decoding.
- Hosting trade-offs. While activating 23B parameters reduces per-token matrix compute, local deployment still requires storing the complete 428B weights shard on disk.
Benchmark evaluation
| Benchmark | Target Capability | M3.1 Flash Score |
|---|---|---|
| DeepSWE v1.1 | Complex software engineering | 73.7% |
| OSWorld V2 | Operating system & computer use | 61.7% |
| BankerToolBench | Multi-step tool use in finance | 76.2% |
| CyberGym | Vulnerability reproduction | 82.2% |
| Agents' Last Exam | Complex professional workflows | 29.6% |
Sources
Did this land? Leave a reaction.
Discussion
0 commentsMembers can join the discussion
Become a member to comment and reply to other members.
Become a MemberNo comments yet
Be the first to start the discussion.