Summarize with AI


Baidu Research open-sourced ERNIE 5.5 Flash Base, a 280-billion parameter mixture-of-experts (MoE) model that activates only 14 billion parameters (5%) per token. Model weights are available immediately on Hugging Face.
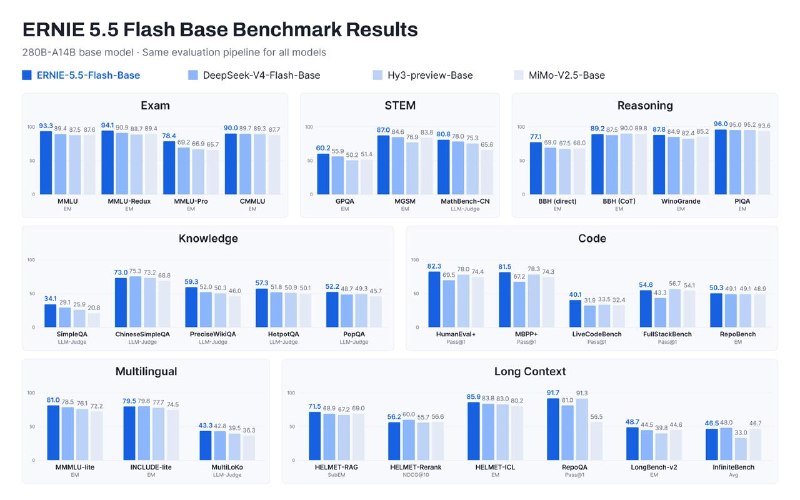
The model introduces architectural optimizations targeting inference efficiency and memory footprints in production deployments. Latent-Gated Sparse Attention compresses KV-cache consumption across extended context windows, while Multi-Router Latent MoE coordinates expert dispatching without added routing compute.
Baidu also integrated ECHO, an architectural layer that blends multi-token prediction heads directly into the base network to accelerate speculative decoding. Training leveraged Baidu's custom Muon distributed optimizer and the FlashMask-4 attention kernel.
What it is
- MoE parameter routing. Holds 280 billion total parameters while activating 14 billion parameters (5%) per forward token pass.
- Latent-Gated Sparse Attention. Reduces KV-cache memory requirements while maintaining retrieval fidelity across long-context queries.
- Multi-Router Latent MoE. Routes expert subsets using parallel latent routers to improve expert assignment without latency penalties.
- ECHO decoding. Unifies multi-token prediction for native speculative decoding speedups during generation.
- Open weights. Base model weights are available on Hugging Face, with fine-tuned instruct variants scheduled for release later.
Sources
Did this land? Leave a reaction.
Discussion
0 commentsMembers can join the discussion
Become a member to comment and reply to other members.
Become a MemberNo comments yet
Be the first to start the discussion.